RoboColosseum and the Race to Measure Physical Intelligence in the Wild
What RoboColosseum measures in the wild: Open and Fine-tune tracks, partial progress scores, Kendall’s W across embodiments, and Unitree G1 results in context.
Language models got Chatbot Arena. Robot policies are harder. A chatbot answer is a string you can rate; a robot policy is a closed loop with the physical world, where every action changes the next observation. Lighting, camera pose, object placement and hardware wear all move the result. That is why a single lab’s success rate on a fixed shelf of tasks is a weak signal of “physical intelligence”.
RoboColosseum is a 2026 attempt to measure that signal at scale in the wild. The accompanying paper (Nguyen, Wang, Shailesh et al., arXiv:2611.02497) is an arXiv preprint and has not been peer-reviewed [1]. It describes a distributed evaluation network spanning offices, homes, campuses and factories, with full-time operators, shared policy serving, and two complementary tracks. The initial study ran from 17 September to 28 October 2026 and covers five vision-language-action (VLA) policies plus three frontier AI agents across four embodiments [1].
This article explains what the benchmark actually measures — especially partial progress and Kendall’s W — and reads the Unitree G1 results the way the authors do: as outcomes under this protocol, not as a general verdict on the product.
From RoboArena to RoboColosseum
RoboColosseum builds on RoboArena, a 2025 distributed evaluation framework for generalist policies on the DROID/Franka platform [2]. RoboArena (Atreya, Pertsch, Lee et al., arXiv:2506.18123; arXiv preprint) crowd-sourced double-blind pairwise comparisons: evaluators freely chose tasks and scenes, ran two anonymised policies back-to-back under matched local conditions, and reported preferences. Across 612 pairwise real-robot comparisons at seven academic institutions, the authors argued that aggregating those preferences ranked generalist policies more accurately than a conventional fixed single-site suite, relative to an exhaustive “oracle” ranking [2].
RoboColosseum keeps the pairwise, in-the-wild idea and expands it along three axes [1]:
- More embodiments: SO-101, Franka in the DROID configuration, Bimanual-YAM, and the Unitree G1 humanoid.
- Two tracks: an Open Track (no task-specific adaptation) and a Fine-tune Track (fixed demonstration budget).
- Operational scale: the paper reports 5,699 Open Track pairwise comparisons across 124 sites, plus Fine-tune evaluations on 20 tasks (five per embodiment) [1].
Founding contributors listed in the preprint include groups at NUS, Hugging Face, the Singapore Embodied AI Centre and BitRobot. The project pledges 10,000 hours of free evaluation time for academic partners [1].
The two tracks, simply
Open Track — generalisation without fine-tuning
An evaluator invents a feasible task with local objects, writes a language instruction, and receives two anonymised eligible models. Both run on the same robot and setup. The evaluator records a preference (A wins, B wins, or tie), progress scores, free-form feedback and a difficulty rating from 1 to 10 [1].
Because tasks vary wildly in difficulty, raw win rates would be misleading. RoboColosseum ranks Open Track systems with a Difficulty-Calibrated Rasch (DCR) model: each policy gets a latent ability, each task a latent difficulty, and human difficulty ratings act as a prior over that difficulty. Success outcomes then update both. For the public board, abilities are mapped to an Elo-style scale; the mapping is linear and does not change the ordering [1].
Active matchmaking (inspired by Chatbot Arena) concentrates new trials on uncertain model pairs. In the authors’ analysis, active matchmaking reaches about 90% agreement with the full-data ranking after roughly 400–500 evaluations, versus about 1,000 under uniform sampling [1].
Fine-tune Track — adaptation under a fixed data budget
Here the question is different: given the same 100 teleoperated demonstrations per task, how well does each VLA adapt? Each policy uses its official fine-tuning recipe until convergence; the data and evaluation protocol stay fixed, while training details may differ by architecture [1]. After fine-tuning, each policy–task pair gets N = 25 evaluation trials [1].
Tasks span pick-and-place, stacking, reorientation, articulated objects, deformable objects, pouring, tool use, bimanual coordination and loco-manipulation on the G1 [1].
What “partial progress” means
Binary success is harsh. A policy that closes a laptop almost all the way and one that never touches the lid both score zero if full closure is required. RoboColosseum therefore defines task-specific progress criteria — a checklist of intermediate milestones for each task [1].
For a rollout, let K be the number of criteria and s the number satisfied (order does not have to be fixed). The rollout’s normalised progress is s / K. Averaging over the N trials gives the progress score (PS). Separately, the success rate (SR) is the fraction of trials that meet the full success definition [1]:
- PS answers: how much of the task did the policy complete on average?
- SR answers: how often did it finish?
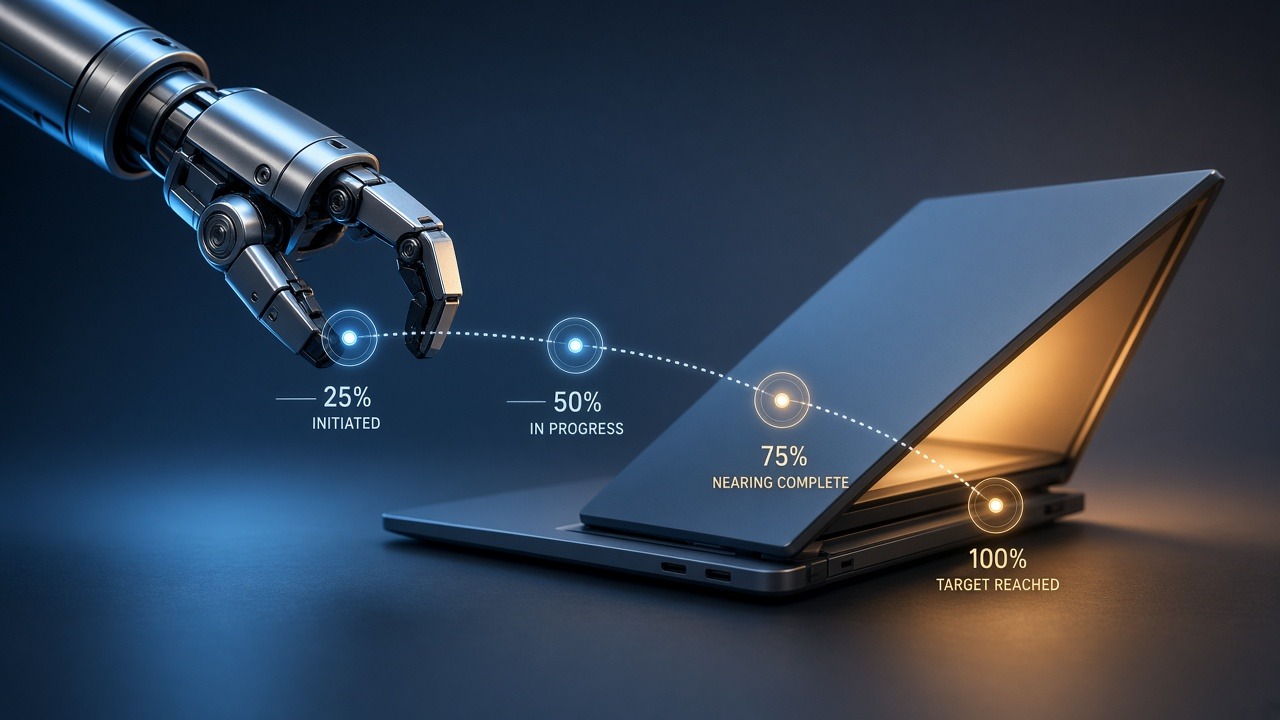
That distinction matters most on hard embodiments. On the Fine-tune Track’s Unitree G1 suite, no evaluated policy completes any of the five tasks (SR = 0% for every model–task pair in the reported table). Average progress scores still separate them: roughly 13.3% to 23.2% across the five policies [1]. Partial progress is how the benchmark says “everyone failed the finish line, but not everyone failed the same way.”
What Kendall’s W means
After fine-tuning, the authors ask whether the same policies rank similarly across the four embodiment-specific task suites. They report Kendall’s coefficient of concordance W = 0.24 [1].
In plain language: Kendall’s W measures how much several rankings agree. It runs from 0 (no agreement — rankings look random relative to each other) to 1 (perfect agreement — every embodiment orders the policies the same way). A value of 0.24 means weak agreement. Knowing who wins on SO-101 does not reliably tell you who wins on Franka, Bimanual-YAM or G1 under this Fine-tune protocol [1].
Concrete examples from the preprint’s Fine-tune averages [1]:
- GR00T N1.7 leads on SO-101 (average PS about 89%, SR about 82%) but is mid-pack on Franka and YAM.
- π0.5 leads on DROID/Franka (PS about 91%, SR about 84%) and on Bimanual-YAM (PS about 97%, SR about 94%).
- Rankings also flip between Open Track and Fine-tune Track on the shared embodiments; open-world strength does not reliably predict post-adaptation strength [1].
For teams buying or fine-tuning a foundation policy, that is the practical takeaway: embodiment- and task-specific evaluation still matters. A single leaderboard number is not enough.
Reading the Unitree G1 result carefully
The Fine-tune Track evaluates five loco-manipulation-style tasks on a Unitree G1 configured for this benchmark (parallel grippers; Pico VR teleoperation for the 100 demonstrations; shared observation and action specs across sites) [1]. Reported average progress scores under that protocol [1]:
| Policy (Fine-tune Track, G1 average) | Progress score (PS) | Success rate (SR) |
|---|---|---|
| LingBot-VLA v2 | 23.2% | 0% |
| GR00T N1.7 | 22.7% | 0% |
| MolmoAct2 | 19.8% | 0% |
| π0.5 | 16.3% | 0% |
| G0.5 | 13.3% | 0% |
These numbers are not a general verdict on the Unitree G1 as a product. They are outcomes for specific fine-tuned VLA checkpoints on five RoboColosseum tasks, with this hardware configuration, these demonstrations, these progress criteria and these safety-stop rules [1]. A different controller stack, different teleoperation quality, different tasks or a vendor’s proprietary autonomy stack could look entirely different. The honest reading is narrower: under this public Fine-tune protocol, current generalist VLAs make only modest partial progress on these G1 tasks and do not complete them.
That reading is still useful. It shows why humanoid loco-manipulation is a stress test for VLA foundation models, and why progress metrics belong beside success rates when the finish line is rarely crossed.
What else the Open Track shows
A few high-level findings from the preprint’s Open Track analysis, each scoped to the collected comparisons [1]:
- Frontier agents can be competitive with specialised VLAs on manipulation progress in pairwise settings, but the advantage depends on which agent and which embodiment. Across 901 paired agent-versus-VLA evaluations, agents made more progress in 394 comparisons, VLAs in 265, with 242 ties [1].
- Relative strength is not reliable completion. Even strong relative systems often post low absolute success on open-world categories; the paper reports that no evaluated system exceeded 13% success in any of its six manipulation categories under the Open Track slice analysed [1].
- Harder tasks break earlier. Full-task success falls from about 30.7% on human-rated difficulty 1–4 to about 0.4% on difficulty 9–10, and mean normalised progress falls from about 56.6% to about 3.5% across the same bands [1].
Together with the Fine-tune results, the picture matches what many labs already feel day to day: demos impress, but consistent completion across wild environments remains scarce — which is also why sim-to-real tooling and post-imitation RL layers keep attracting attention.
Ranking reliability is itself a measured quantity
A distributed benchmark is only as trustworthy as the agreement between different slices of its network. RoboColosseum checks this by repeatedly splitting evaluation sites into two disjoint halves, fitting DCR on each half, and measuring how often model-pair orderings agree [1]. On DROID/Franka and Bimanual-YAM, mean pairwise ranking agreement is about 85% (mean Spearman ρ about 0.82). On SO-101 it is lower — about 59% agreement and ρ about 0.30 — so that embodiment’s Open Track ordering is more sensitive to which sites contribute [1].
Scale helps. Random subsets of the Open Track reach about 90% mean agreement with the full 5,699-comparison ranking near 1,123 evaluations, and about 95% near 4,755, though the percentile band around those means stays wide [1]. In other words: a few hundred well-chosen pairwise trials already recover much of the leaderboard on average, but high-confidence stability still wants thousands of physical comparisons.
That statistical honesty is part of what separates a measurement programme from a marketing shoot. It also explains the project’s pledge of free academic evaluation hours: more diverse sites reduce the chance that one lab’s lighting and clutter define “state of the art” [1].
Why this kind of benchmark matters
RoboColosseum will not replace careful single-factor studies. The authors say as much: coverage still depends on which checkpoints and robots can participate, the Fine-tune Track currently uses five tasks per embodiment, and allowing each model’s official fine-tuning recipe means the track measures end-to-end adaptation from shared data rather than a perfectly identical optimiser [1]. Pairwise in-the-wild evaluation also trades experimental control for diversity — the same trade-off RoboArena embraced [2].
What it does offer is a shared, growing ruler. Physical intelligence needs something like that if the field wants to tell marketing videos apart from reproducible gains. Partial progress keeps signal when success rates are near zero. Kendall’s W warns against over-generalising a win on one arm. And stating the Unitree G1 numbers as benchmark-conditioned results, not product scores, is how that ruler stays honest.
Bottom line
RoboColosseum is less a single leaderboard than a measurement programme: open-world pairwise battles, controlled fine-tuning races, progress checklists and cross-embodiment concordance tests. The first snapshot (late 2026, preprint) already shows frontier agents jostling with VLAs, weak ranking agreement across embodiments (W = 0.24), and humanoid loco-manipulation where partial progress exists but full success does not under the stated protocol. Treat every number as conditional on the robots, tasks and rules that produced it — and the benchmark becomes useful rather than theatrical.
Related reading
- Vision-Language-Action Models: The New Foundation Layer for Robots
- Sim-to-Real in 2026: Closing the Gap Without Endless Real-World Data
- After Imitation: Residual and Real-World RL as the Next Layer for Robot Policies
References / Sources
- Tan Sang Nguyen, Yi Ru Wang, Shailesh Shailesh et al. — “RoboColosseum: Evaluating Physical Intelligence at Scale In-The-Wild”, arXiv:2611.02497 (arXiv preprint, not peer-reviewed). Evaluations reported for 17 September–28 October 2026. https://arxiv.org/abs/2611.02497
- Pranav Atreya, Karl Pertsch, Tony Lee et al. — “RoboArena: Distributed Real-World Evaluation of Generalist Robot Policies”, arXiv:2506.18123 (arXiv preprint). https://arxiv.org/abs/2506.18123 · https://robo-arena.github.io
- Related reading: AndBeyond.Tech — Vision-Language-Action Models: The New Foundation Layer for Robots.
- Related reading: AndBeyond.Tech — Sim-to-Real in 2026: Closing the Gap Without Endless Real-World Data.
Images: original illustrations generated for AndBeyond.Tech; no logos or real people depicted.