Open-Weight Frontier Models vs Closed APIs: The Sovereignty Trade-Off
Open-weight LLMs trail closed APIs by months, not years. How to mix self-hosted models, hosted open weights and closed APIs for AI sovereignty and cost.
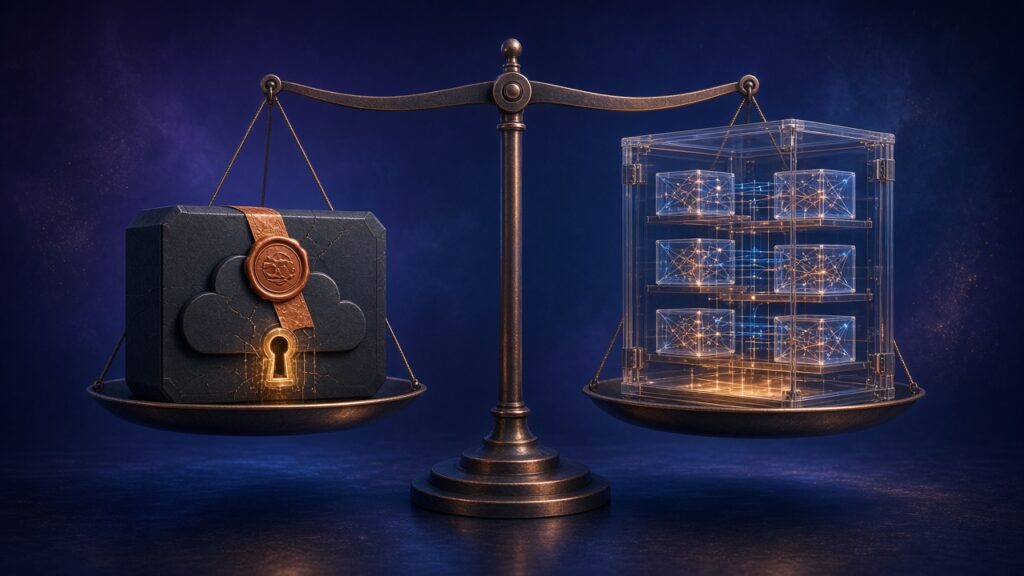
Choosing between open-weight models you can host and closed frontier APIs is less a beauty contest than a sovereignty, cost, and control decision.
Enterprise AI teams no longer face a binary “use GPT or build nothing” fork. Open weight LLM releases from multiple labs sit a few months behind the closed frontier on aggregate capability indices, while developer platforms route tens of trillions of tokens through self-serve open endpoints. At the same time, enterprise LLM dollars still cluster on closed APIs. The real question for 2026 is not which camp “wins,” but which mix of self-hosted AI models, hosted open-weight inference, and closed APIs matches your AI sovereignty, compliance, and unit-economics constraints.
This article maps the trade-off with public evidence: how close open weights are on capability, where tokens and dollars actually go, what “open” means under European rules, and which decision criteria survive contact with GPUs, edge silicon, and auditors.
What “open” actually means in 2026
“Open weight” is not a synonym for open source. Weights may be downloadable under Apache- or MIT-style licenses, under custom community licenses with usage caps, or under terms that forbid certain commercial uses. Architecture cards, training recipes, and dataset inventories sit on a separate axis. The Open Source Initiative’s Open Source AI Definition remains a stricter bar than “weights on a hub,” and many popular releases do not meet it—even when they are highly usable in production.
European product law now forces the vocabulary into sharper focus. Under the EU AI Act’s Article 53(2) pathway for general-purpose AI models, providers that release a model under a free and open-source licence—with parameters including weights, architecture, and usage information publicly available—may be exempt from some documentation duties toward authorities and downstream providers, and from appointing an authorised representative for non-EU providers. Those exemptions do not apply to models classified as systemic-risk GPAI. Even when the documentation exemptions apply, copyright-compliance policy and a sufficiently detailed training-content summary remain required. For buyers, the practical lesson is blunt: treat “open” as a compliance checklist, not a marketing adjective.
License text still matters even when weights are public. Apache-2.0 and MIT-style grants travel cleanly through most enterprise legal review. Custom community licenses—common among large Llama-family and some Mistral-line releases—can restrict use by competing model providers, impose acceptable-use policies, or change the redistribution story for products you ship. Treat the licence file as a first-class artifact beside the GGUF or safetensors shard: if legal cannot clear it for your MAU band or geography, the model is not “available” for production no matter how strong the eval chart looks.
Self-hosting adds another layer. Running weights in your VPC, on-prem, or air-gapped environment buys data residency and inspectability that a multi-tenant frontier API cannot match. Hosting the same open weights through a third-party inference API buys convenience and elasticity—but reintroduces a provider boundary. Portfolio design should name which of those three surfaces each workload uses: closed frontier API, hosted open-weight API, or self-hosted / on-device.
Capability: a durable lag, not a chasm
Epoch AI’s Epoch Capabilities Index (ECI) tracking shows that, since January 2026, the most capable open-weight models have lagged state-of-the-art closed models by an average of about four months, with an average ECI gap of roughly eight points—on the order of the gap Epoch associates with successive closed releases such as GPT-5 versus GPT-5.5. That is a planning number, not a death sentence. Four months is short enough that fine-tuning, retrieval, tool use, and cascade routing often close the product gap for defined tasks, and long enough that teams chasing absolute frontier reasoning, multimodal depth, or brand-new agent features will still prefer closed APIs for the tip of the stack.
Mixture-of-Agents research illustrates the other side of the ledger: layered collaboration among open models can exceed a single strong closed baseline on preference benchmarks. In the 2024 Together / academic MoA paper, an open-model-only Mixture-of-Agents reached 65.1% length-controlled win rate on AlpacaEval 2.0 versus 57.5% for GPT-4 Omni in that comparison—evidence that orchestration, not only parameter count, moves the Pareto frontier. Cascades cut the other way on cost: FrugalGPT (2023) showed that routing queries across heterogeneous LLM APIs can match a top individual model’s accuracy with up to about 98% cost reduction on the HEADLINES finance-news task in that study (about 73% on OVERRULING and about 59% on COQA), or improve accuracy at the same spend. Those papers predate today’s model cards, but the architectural lesson is evergreen: route, do not fetishize a single endpoint.
Tokens versus dollars: two different markets
Usage telemetry and enterprise spend tell different stories—and both matter for sovereignty planning.
As of late 2025, OpenRouter’s State of AI study—built on roughly 100 trillion tokens of platform traffic through that window—finds open-weight models reaching about one-third of token volume by period end, with Chinese open families (DeepSeek, Qwen, and peers) contributing a large share of that open slice after mid-2025 release waves. Roleplay and programming dominate open-weight category mix on that platform; proprietary models still carry much of the highest-stakes coding and knowledge work. The dual structure is durable: closed systems define the reliability ceiling many enterprises buy; open systems absorb cost-sensitive and customization-heavy volume.
Enterprise dollar share looks more conservative. As of Menlo Ventures’ 2025 State of Generative AI in the Enterprise, generative AI spend is about $37 billion, including roughly $12.5 billion on foundation-model APIs. Open-source / open-weight models account for about 11% of enterprise LLM API usage in that survey frame—down from about 19% the prior year—while Anthropic, OpenAI, and Google together take the vast majority of paid enterprise API share. Chinese open models remain a thin slice of enterprise API dollars even as they surge among developers. Menlo’s mid-year 2025 update similarly put closed models behind the large majority of enterprise workloads and described open performance as trailing the closed frontier by roughly nine to twelve months in that window.
Those lag figures are not contradictory so much as non-comparable. Epoch’s ~four-month / ~eight-point ECI gap is a continuous, aggregate capability-index measure covering open versus closed releases since January 2026. Menlo’s nine-to-twelve-month estimate is an earlier, survey-and-market framing of enterprise-relevant open performance versus the closed tip as of mid-2025. Different clocks, different methods, same directional story: open weights trail the closed frontier, and the gap is measured in months—not years.
Read together: self-hosted AI models and open APIs are winning mindshare and token share where price, customization, and experimentation dominate; closed APIs still win where procurement, support SLAs, and peak quality dominate. Sovereignty programs that only watch one of those charts will mis-size the stack.
Cost, control, and compliance
Cost is not “API price × tokens”
Closed APIs convert marginal tokens into opex with almost no capacity planning. Self-hosting converts the same work into GPU depreciation, power, networking, SRE time, evaluation harnesses, and security patching. Hosted open-weight APIs sit in between: you pay someone else’s utilization curve but keep model choice. Cascades and small specialist models (including quantized mid-size open weights) often beat “always call the frontier” on cost-per-successful-outcome—the metric FrugalGPT and MoA both push teams toward.
Jevons-style effects still apply. As open and closed inference get cheaper, total token demand rises. Menlo’s 2025 commentary already expected net generative-AI spend to keep climbing even as unit inference costs fall. Sovereignty does not automatically mean “cheaper”; it can mean “predictable,” “auditable,” or “air-gappable.”
A useful internal metric is cost per accepted outcome: successful ticket resolution, correct extraction, or human-approved draft—not raw dollars per million tokens. Closed frontier calls that finish a hard case in one shot can beat a thrifty open cascade that retries five times and still escalates to a human. Conversely, routing ninety percent of easy traffic to a quantized mid-size open model can fund the ten percent that truly need the closed tip. Measure both legs before declaring a winner.
Control and inspectability
Weights you hold can be hashed, version-pinned, red-teamed offline, fine-tuned on regulated corpora, and run without sending prompts to a third country. Closed APIs give you contractual controls, regional endpoints, and zero-retention options—but not bit-level inspectability of the model you called yesterday. For high-assurance environments, that distinction is the core of AI sovereignty: who can change the model, who can see the prompts, and who can prove which artifact produced a decision.
Compliance is workload-scoped
Air-gapped inference helps with data residency; it does not erase training-data provenance questions, copyright policy duties for GPAI providers, or sector rules on automated decisions. EU AI Act open-source exemptions narrow some GPAI documentation burdens; they do not create a free pass for systemic-risk models or for deployers of high-risk AI systems. Procurement language should require: license compatibility for your use case, a named model card and evaluation suite, logging of model IDs and prompts in your control plane, and a documented fall-back if a closed provider changes terms or regions.
Hardware: the silent gate on self-hosting
Sovereignty fantasies die on memory bandwidth and KV-cache capacity. Primary accelerator specs set the ceiling: NVIDIA’s H200, for example, ships with 141 GB of HBM3e and 4.8 TB/s of memory bandwidth—nearly double H100 capacity and about 1.4× its bandwidth—and NVIDIA cites up to about 2× faster Llama-2-class inference versus H100 on published workload notes. Frontier-class open MoE checkpoints still want multi-GPU nodes, high-speed interconnect, and serious inference engineering. Serving software matters as much as silicon: the vLLM / PagedAttention line of work showed 2–4× throughput gains versus prior systems at comparable latency by paging the KV cache and enabling continuous batching—exactly the kind of utilization you need before self-hosting pencils out.
Mid-size open models in the roughly 15B–70B band—OpenRouter’s “medium is the new small” cohort as of late 2025—are where many enterprises find deployable quality on a single high-memory accelerator or a small cluster. Sub-15B and heavily quantized variants push further onto workstations and edge devices when latency, offline operation, or per-query cost dominates.
That is why badges for Edge & On-Device AI and AI Accelerators & Silicon belong on this topic. On-device and near-edge inference shrink the trust boundary: prompts never leave the premises, and silicon choice (GPU, NPU, custom accelerator) becomes part of the product. Menlo’s enterprise surveys already flagged models moving to the edge for privacy, latency, and zero marginal API cost. The trade-off is capability headroom: edge silicon rarely hosts the absolute frontier. Hybrid designs keep a closed or large open teacher in the cloud for hard cases and a local student for the common path.
Decision criteria for 2026 (evergreen checklist)
Use the following tests per workload, not per company slogan:
- Data boundary. Must prompts and embeddings stay inside a named jurisdiction or air gap? If yes, prefer self-hosted or strictly regional private endpoints; treat public multi-tenant APIs as a last resort.
- Capability ceiling. Does the task need the current closed frontier (novel agent tools, hardest reasoning, multimodal edge cases)? If yes, buy the closed API for that slice and keep open weights for the long tail.
- Volume shape. Is the workload high-QPS, repetitive, and evaluable? Cascades, mid-size open models, and caches usually win unit economics.
- Change control. Do you need to freeze weights for validation (medical, industrial, safety cases)? Open weights you pin beat opaque weekly API revisions.
- License and Act fit. Confirm the licence allows your MAU, geography, and redistribution story; map GPAI duties if you redistribute or substantially modify.
- Ops maturity. Do you have GPU SRE, eval regression, and incident response for model serving? If not, hosted open-weight APIs are a stepping stone—not a failure.
- Exit option. Can you swap providers in a week? Abstract behind an internal router early; OpenRouter-style multi-model habit is a resilience pattern, not only a price trick.
A sober default for many regulated enterprises in 2026: closed APIs for peak-quality and undifferentiated knowledge work, self-hosted or VPC-hosted open weights for sensitive and high-volume paths, and edge models for offline / ultra-low-latency features—with an internal cascade that promotes only when cheaper tiers fail an automated quality gate.
Bottom line
The sovereignty trade-off is not “open good, closed bad.” Epoch’s ~four-month / ~eight-point ECI lag (since January 2026) says open weights are close enough to matter. OpenRouter’s ~one-third open token share as of late 2025 says developers already vote with traffic. Menlo’s ~11% open share of enterprise LLM usage in its 2025 enterprise survey says money and risk committees still lean closed. EU AI Act Article 53(2) says “open” is a legal status with residual duties, not a vibe.
Teams that win treat open weight LLM choice as portfolio construction: measure capability on your evals, price success not tokens, put silicon where residency demands it, and keep a contractual exit from every closed dependency. AI sovereignty is the ability to prove where inference ran, which artifact decided, and how you would continue if a vendor or a border closed tomorrow.
Related reading
- Computer-Use Agents Enter Production: What Actually Works in the Enterprise
- Inside the AI Accelerator Market: GPUs, Custom ASICs, and Who Wins Inference
- Browser, IDE, and OS: The Three Battlegrounds for AI Interfaces
References
- Open models lag state-of-the-art closed models by 4 months | Epoch AI — Edwards & Emberson; ~4-month lag and ~8-point average ECI gap since January 2026 (aggregate capability index).
- State of AI (OpenRouter / a16z) — Aubakirova et al., Dec 2025 (as of late 2025); ~100T-token study; open-weight share ~1/3 of tokens by period end; category and geography breakdowns.
- 2025: The State of Generative AI in the Enterprise | Menlo Ventures — 2025 enterprise survey: ~$37B genAI spend; ~$12.5B foundation-model APIs; open models ~11% of enterprise LLM usage (from ~19%).
- 2025 Mid-Year LLM Market Update | Menlo Ventures — mid-2025 market update: closed-source dominance of enterprise workloads; open trailing frontier by ~9–12 months (survey/market framing; not the same clock as Epoch ECI).
- How does the AI Act apply to general-purpose AI models released as open-source? | AI Act Service Desk — Article 53(2) exemptions, systemic-risk carve-out, residual copyright and training-summary duties.
- Mixture-of-Agents Enhances Large Language Model Capabilities (arXiv:2406.04692) — Wang et al., 2024; open MoA 65.1% vs GPT-4o 57.5% LC win rate on AlpacaEval 2.0.
- FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance (arXiv:2305.05176) — Chen, Zaharia & Zou, 2023; cascade routing matching best individual LLM accuracy with ~98% cost reduction on HEADLINES, ~73% on OVERRULING, ~59% on COQA.
- NVIDIA H200 GPU — 141 GB HBM3e, 4.8 TB/s bandwidth; up to ~2× Llama-2 inference vs H100 on NVIDIA’s published comparisons.
- Efficient Memory Management for Large Language Model Serving with PagedAttention (arXiv:2309.06180) — Kwon et al. (vLLM); 2–4× throughput vs prior systems at comparable latency via paged KV cache.
Images: original illustrations generated for AndBeyond.Tech; no logos or real people depicted.